01
Understand
the prediction.
Token attribution, mechanistic interpretability, and formal checks of reasoning. Which parts of a model’s input and computation matter?
Explore interpretability HETA · NSF-CoTPh.D. student · University of Florida
Understanding AI.
Building trust.
I study what happens inside AI models—and how to make their decisions and collaborations more reliable.
Advised by Prof. Sumit Kumar Jha
Looking for a Summer 2027 research internship in LLM/VLM interpretability, trustworthy AI, or multi-agent collaboration.
Let’s connect01 / A little about me
A convincing answer is a starting point.
I want to understand the mechanism behind it.
I’m a Ph.D. student in Computer and Information Sciences at the University of Florida, working with Prof. Sumit Kumar Jha. My research connects explanations of model behavior with interventions: from token attribution and machine unlearning to jailbreak defense and reliable agent coordination.
Before UF, I studied at Florida International University, earned my M.Tech. at IIT Bombay, and spent two years developing server firmware at Intel. That path—from hardware to model internals—shapes how I think about dependable AI.
02 / Research directions
Three connected questions guide my work, across language models, vision models, and teams of agents.
Token attribution, mechanistic interpretability, and formal checks of reasoning. Which parts of a model’s input and computation matter?
Explore interpretability HETA · NSF-CoTRepresentation steering, jailbreak analysis, and machine unlearning. How can we change a model’s behavior precisely and responsibly?
Explore model safety Nullspace Steering · Selective AmnesiaDistributed intent, decentralized coordination, and long-horizon control. How do we keep a team of AI agents safe, on task, and in role?
Explore multi-agent systems CITADEL · URCP · ATLAS · ATC03 / Selected publications
8 selected papers
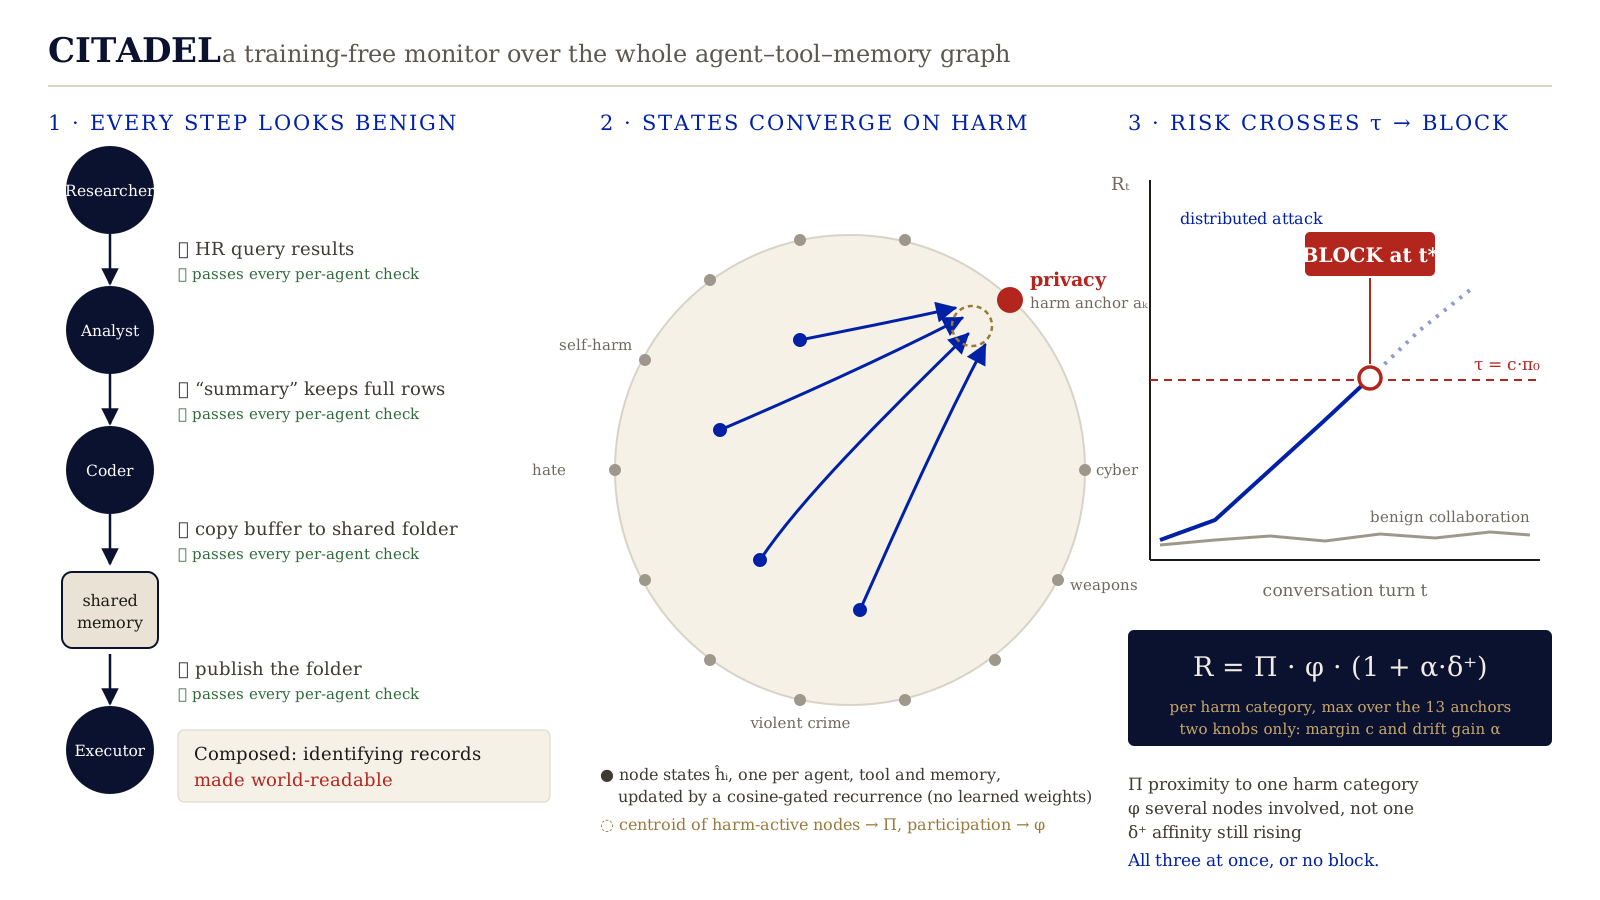 CITADEL
Detecting harmful intent that emerges across agents, tools, and shared memory—even when the individual steps appear harmless.
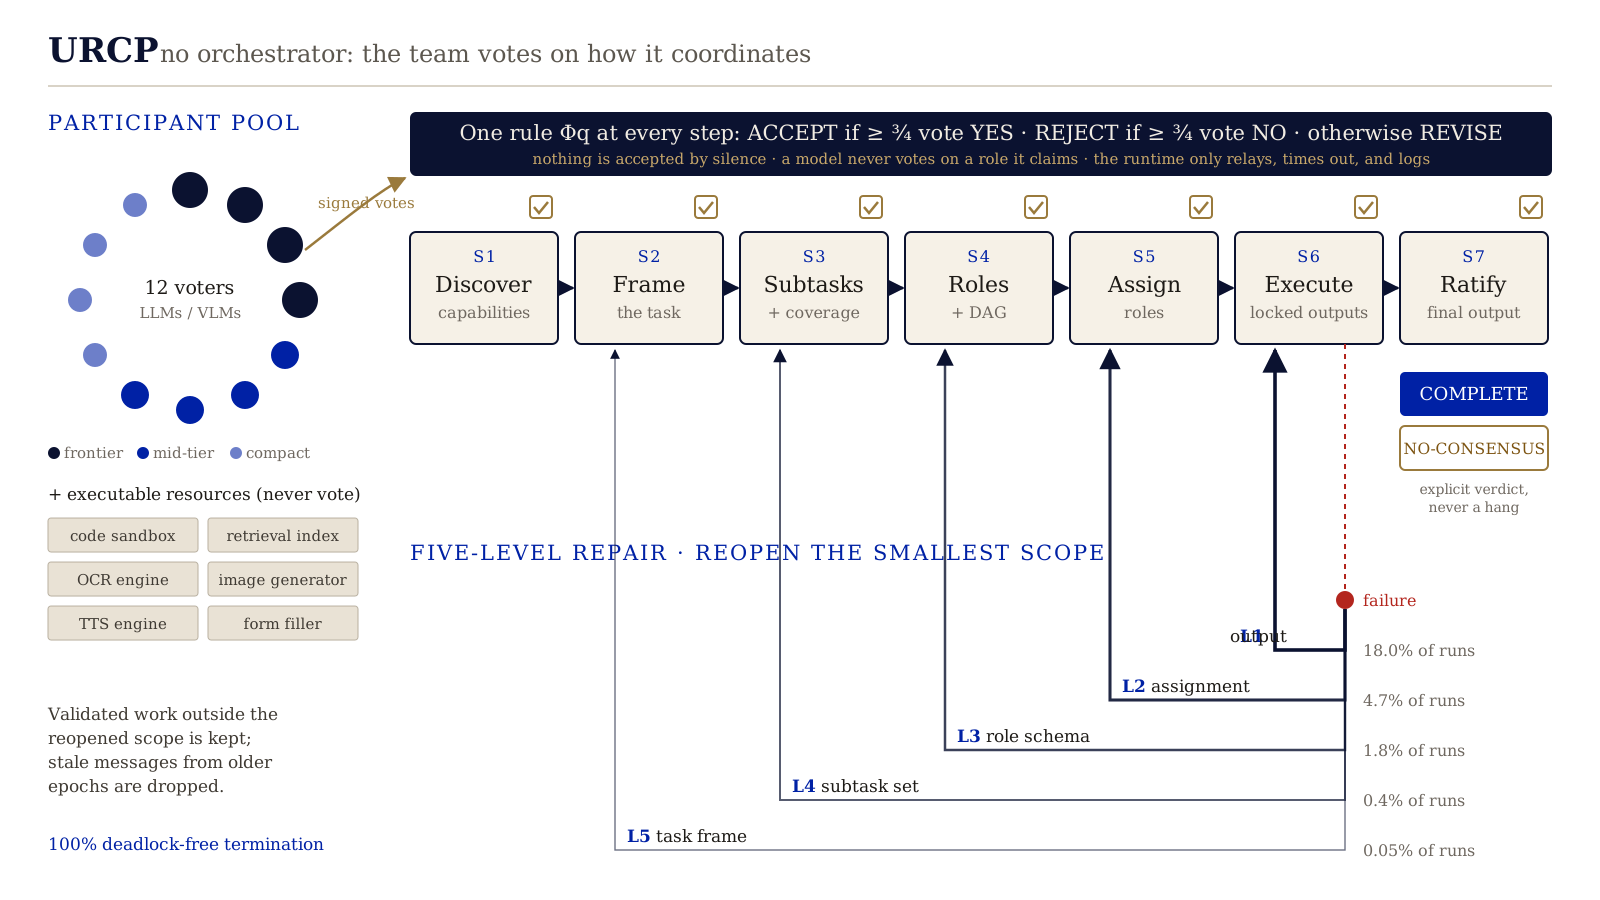 URCP
How can heterogeneous agents agree on roles, share resources, and repair failures without a central orchestrator?
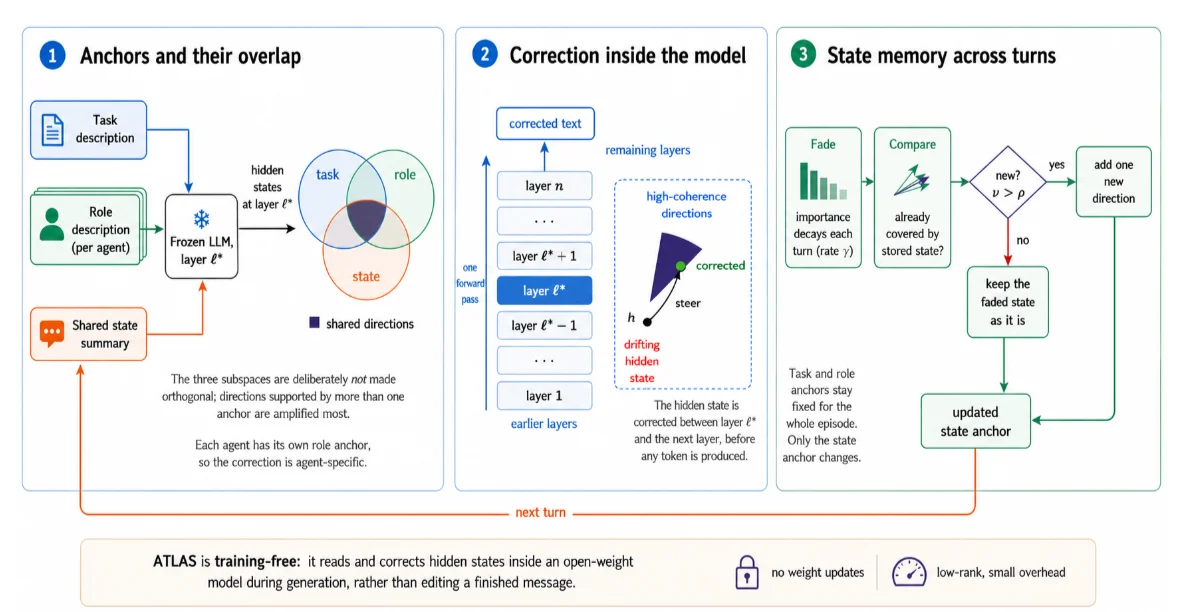 ATLAS
Intervening on hidden representations to keep collaborating agents aligned with their task, role, and shared state.
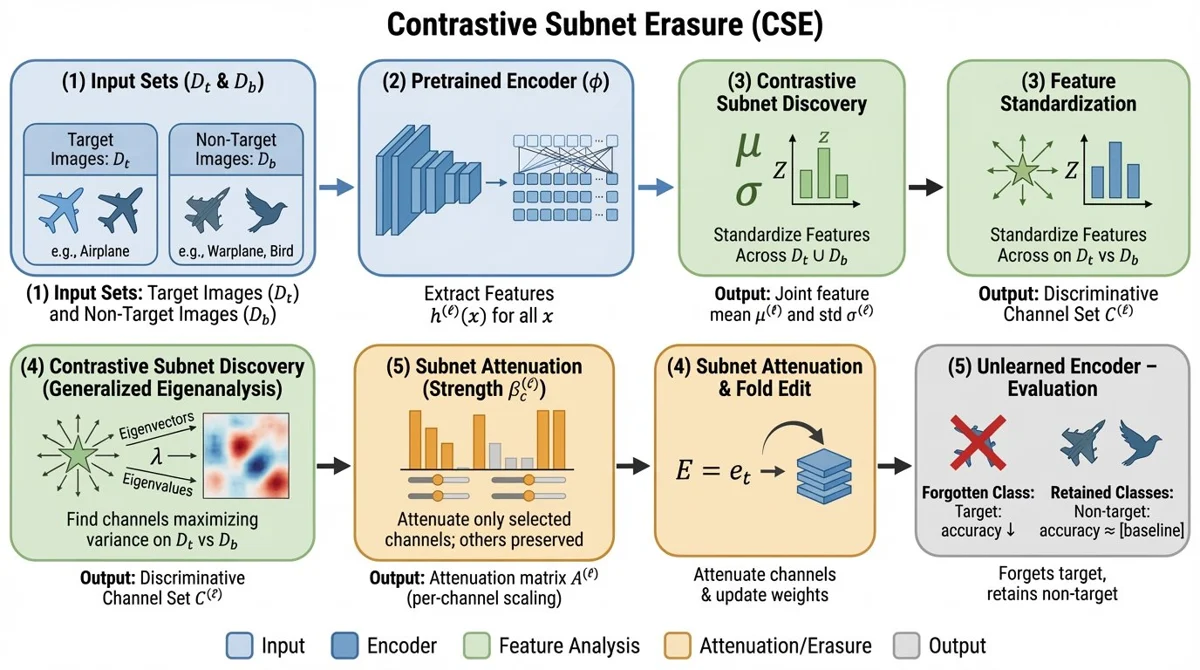 Selective Amnesia
Making vision models forget a selected class through targeted subnetwork modification.
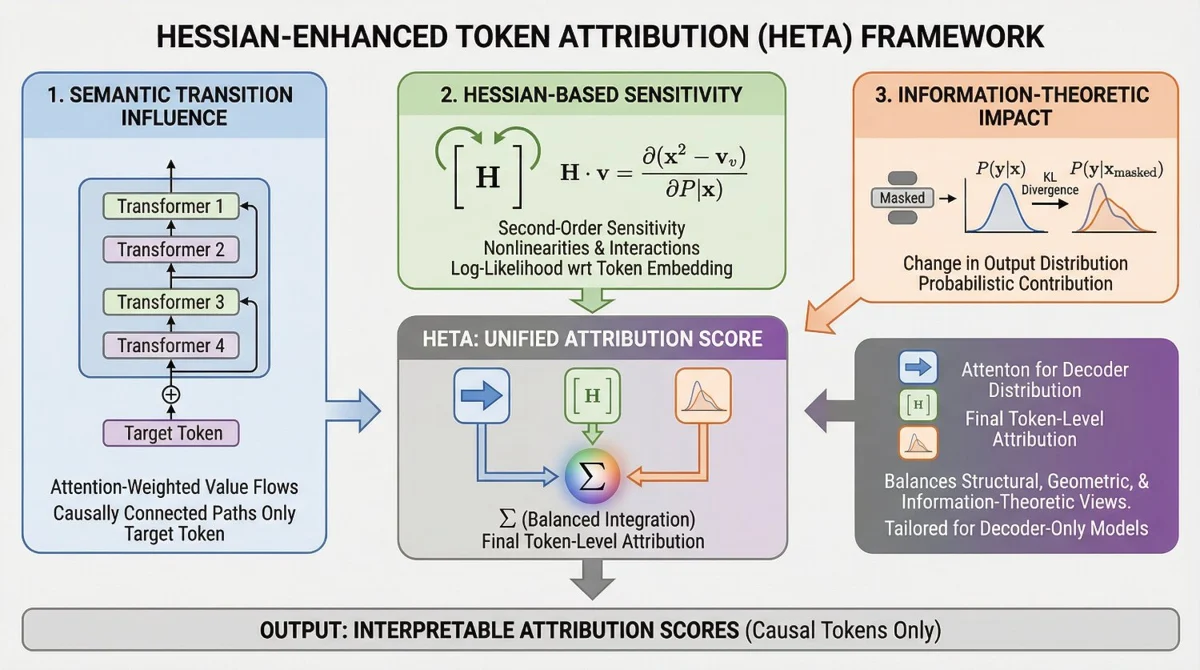 HETA
Understanding which input tokens influence a language model’s predictions through second-order attribution.
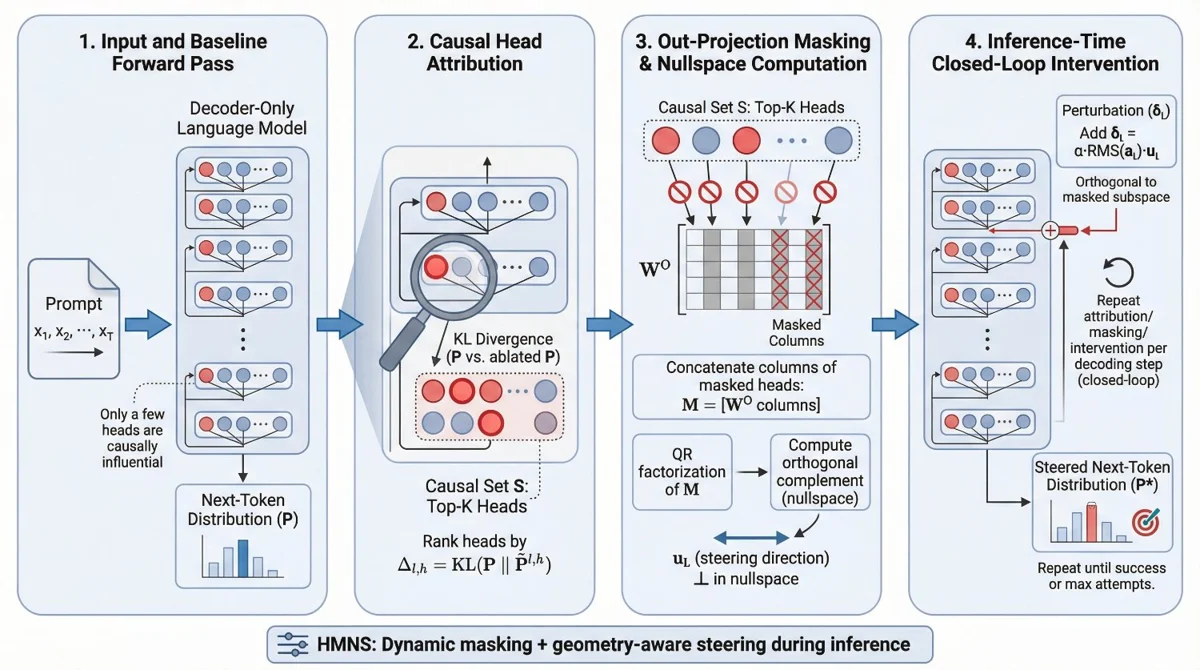 Nullspace Steering
Studying how interventions in internal representation spaces expose vulnerabilities in language-model safety.
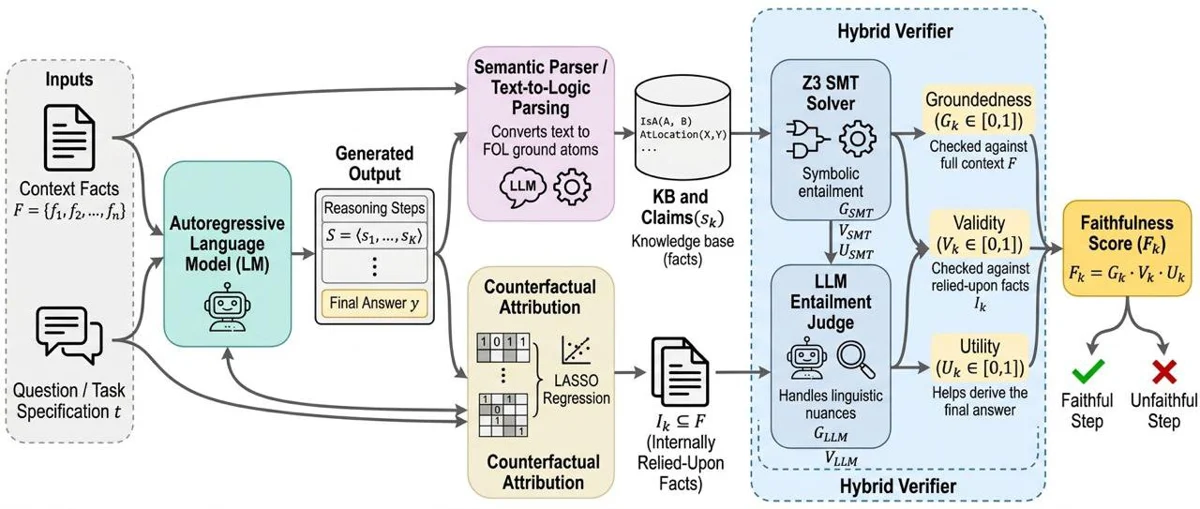 NSF-CoT
Combining neuro-symbolic reasoning and formal checks to examine whether explanations support an answer.
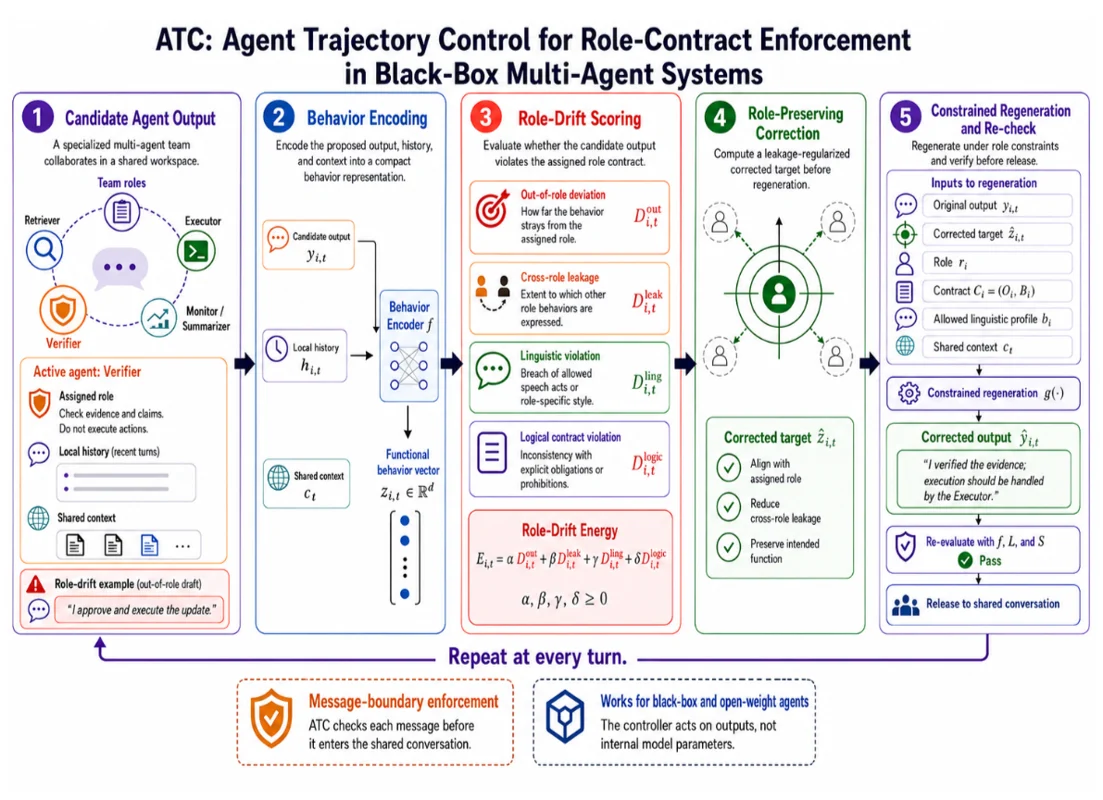 ATC
Enforcing agent role contracts through output scoring and constrained regeneration when model internals are inaccessible.
Explore each paper’s research page, with full PDFs and code linked where available.
04 / The path so far
From server memory to model memory, I’m drawn to understanding how complex systems work.
Read my CV / resumePh.D. student · Graduate Research Assistant
Computer and Information Sciences
Advisor: Prof. Sumit Kumar Jha
Doctoral study · Transferred to UF
Computer and Information Sciences · GPA 4.0/4.0
Silicon Firmware Development Engineer
DDR5 memory initialization, server boot flows, and performance optimization.
M.Tech. · Computer Science & Engineering
GPA 9.01/10 · Certificate of Excellence in Research
B.Tech. · Computer Science & Engineering
GPA 8.9/10
Recognition & service
2026CVPR HighlightClass-level machine unlearning
IIT BombayExcellence in ResearchMaster’s thesis research
2024Second Place Poster AwardIEEE NAECON
ServiceResearch peer reviewICLR · NeurIPS · AAAI · CVPR
05 / Let’s connect
I’d love to work with people asking hard questions about how AI works—and how we can make it more trustworthy.
vishalpramanik@ufl.edu